Public-records data fleet
Scrapers that read public records from city and county web portals and feed them into a CRM.
- Built for
- BuildSource LLC
- Role
- Founder
- Status
- In production
- Stack
- Python, requests, curl_cffi, Beautiful Soup, pandas, pytest
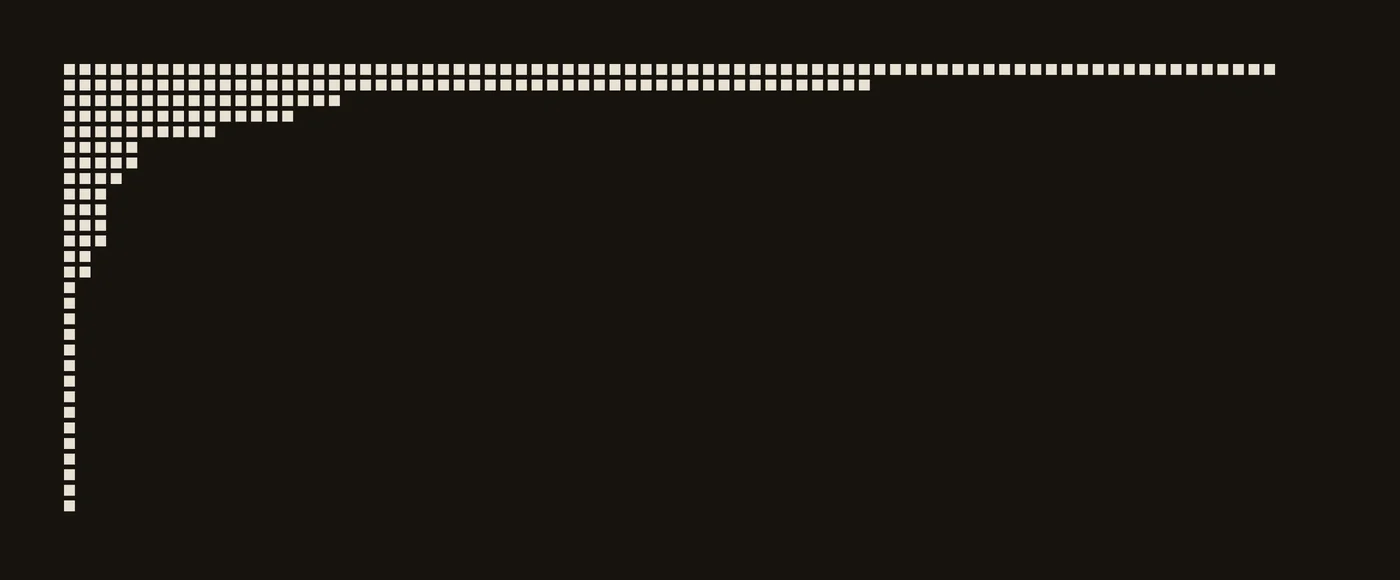
City and county offices publish public records on web portals that run on many different systems, each with its own search, paging and sign-in. I built a fleet of scrapers that reads them every week and turns every record into the same columns, ready for the CRM's database.
The size of the fleet
- scrapers enabled
- 218
- switched on in its roster
- protocols
- across 29
- each a kind of portal it can read
- lines of Python
- about 107,000
- tests included
Shared adapters
Most of the fleet's portals run on a few shared systems, and Tyler EnerGov and Accela are the largest families. The rest run on smaller systems, some of them unique to a single office.
Each protocol maps to an adapter: code that searches its kind of portal and turns every record into the same columns. The roster drives the fleet. An entry names a portal and its protocol, so a portal on a known system needs only an entry, and a new system needs a new adapter.
A portal is switched on only after it passes an onboarding gate: its identity, a sample fetch, its dedupe key and the shape of its rows are checked first.
Bot walls
Some portals sit behind bot protection, so the adapters that need it send their requests with a browser's TLS fingerprint. Requests are throttled per site, and a site that refuses is slowed down for hours; some adapters skip it until then.
Portals that need a signed-in public user get their token from a headless SSO sign-in before the search runs.
Failing loudly
A scraper can look healthy and still bring back too little, so a quiet result is treated as suspect. A portal that pins a known record is probed for it first, and a portal that fails the probe is marked failed instead of handing in an empty pull.
A guard catches searches keyed to the year's case numbers, which would quietly match nothing after the January rollover. On a portal that has to be walked record by record, a saved cursor moves forward only after a fully clean walk, so a failed run never skips a range. In the database, source-health alerts flag a source that goes dark or freezes.
The suite runs with the live network switched off, against stored captures of real portal pages, SSO-gated portals included, with 4,298 tests.
Into the database
Each run writes its rows in the shape the ingester already reads, and they load into the database the Lead Tracker CRM runs on. The fleet runs weekly from a Mac.
Across 705,046 rows ingested from about 230 public sources, that database holds about 589,000 records.
Contact
For a role, a project or a question about anything here, email me.
An AI phone line that answers questions about my work.
- Call my AI
- (213) 635-1440
- Download
- Résumé (PDF)